World Bank’s small-AI push makes the failed connection a product test
The World Bank is emphasizing practical local AI ahead of its Seoul summit. Our analysis asks what a pilot must prove beyond a working model.

Shared editorial profile. Founder Nikolaj Lysgaard is responsible for publication decisions and corrections. Articles may use AI assistance; hands-on work is identified separately. Read our editorial policy.
Editorial responsibility: founder Nikolaj Lysgaard. Sources, corrections and commercial disclosures.
The World Bank is emphasizing practical local AI ahead of its Seoul summit. Our analysis asks what a pilot must prove beyond a working model.
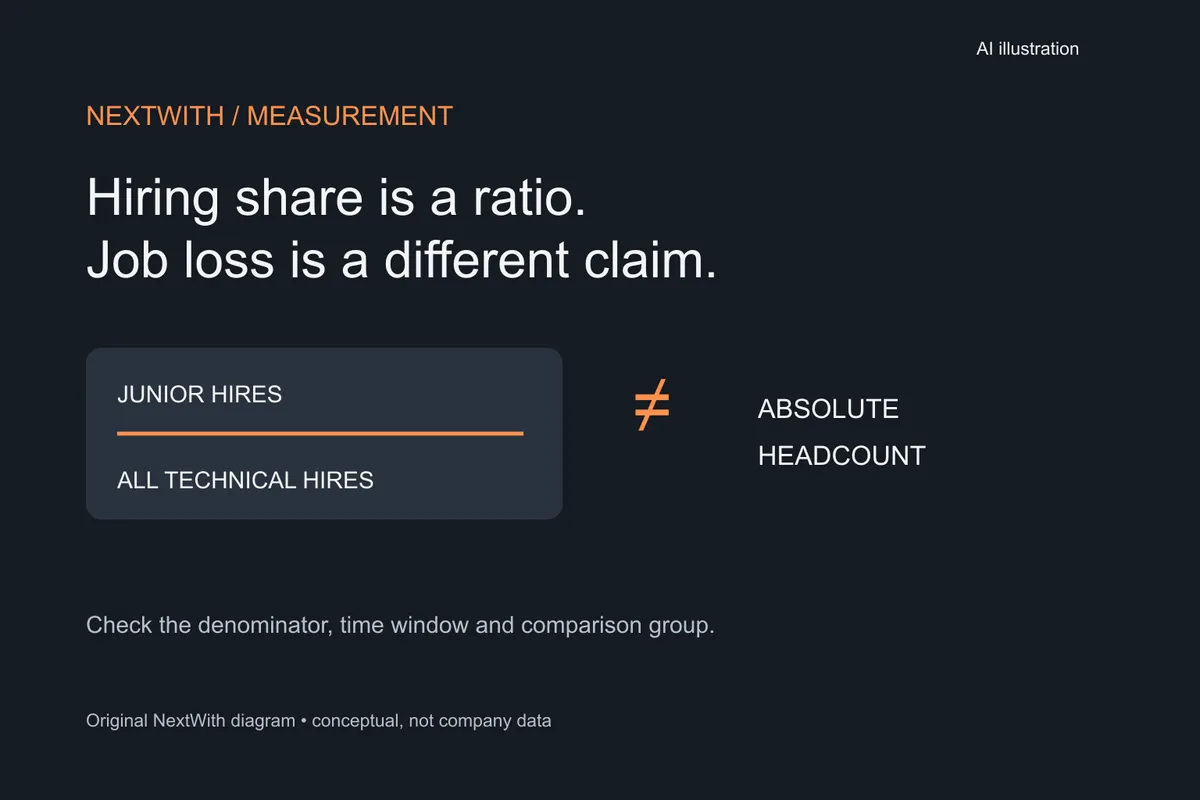
A falling hiring share cannot reveal absolute job losses. Our analysis explains which denominators and comparison groups a workforce decision needs.

Meta’s English commercial-terms preview narrows crawling purposes. The Verge reports a clarification, while our Danish response still showed different wording. Text changes do not establish crawler behavior.

Anthropic describes six embedded METR staff and publication rights with redaction limits. CNBC’s correction separates SecureBio’s narrower review from that arrangement.

Replit’s CEO describes a break with Anthropic, but TechCrunch reports a dispute and Replit documentation still lists Claude options. We separate partnership claims from account access and task behavior.

Paysend’s CEO describes selective AI access and month-long trials. Our analysis separates his productivity estimate from evidence about completed work and narrower workflows.

Apple makes nonconsensual intimate imagery explicit in moderation rules and clarifies sanctions for hidden features. Our analysis examines what evidence of an effective reporting process would look like.

Two expanded partnerships point to a shared Nvidia driving stack. Our analysis separates the announced architecture from customer availability and evidence of real-world performance.

Glimpse revisits visual evidence while reasoning. Its launch raises practical questions about benchmark scope, task cost and access; we explain how to evaluate those separately.

Vercel reports rapid Jev adoption within its gateway. Team reach, spending share and return rates measure different things; none alone establishes global market leadership.

The reported Chrome extension update expands tab context and browser actions. Our analysis separates a reading task from an authorized action and explains what remains untested.

Analysis of one internal training incident: why a successful deployment and authorized resource use need separate acceptance checks. This is a retrospective case, not a claim about all agents.

Muse Spark Open brings a multi-Mac deployment option for a large open-weight model. Reported hardware requirements, licensing and operational performance need separate checks.